
Lock the look with one image, then animate it on three video models
Make one approved image, then use it as first_frame on wan-3.0, kling-3 and minimax-h3-max. Same start, three motions, one prompt, so you can compare.
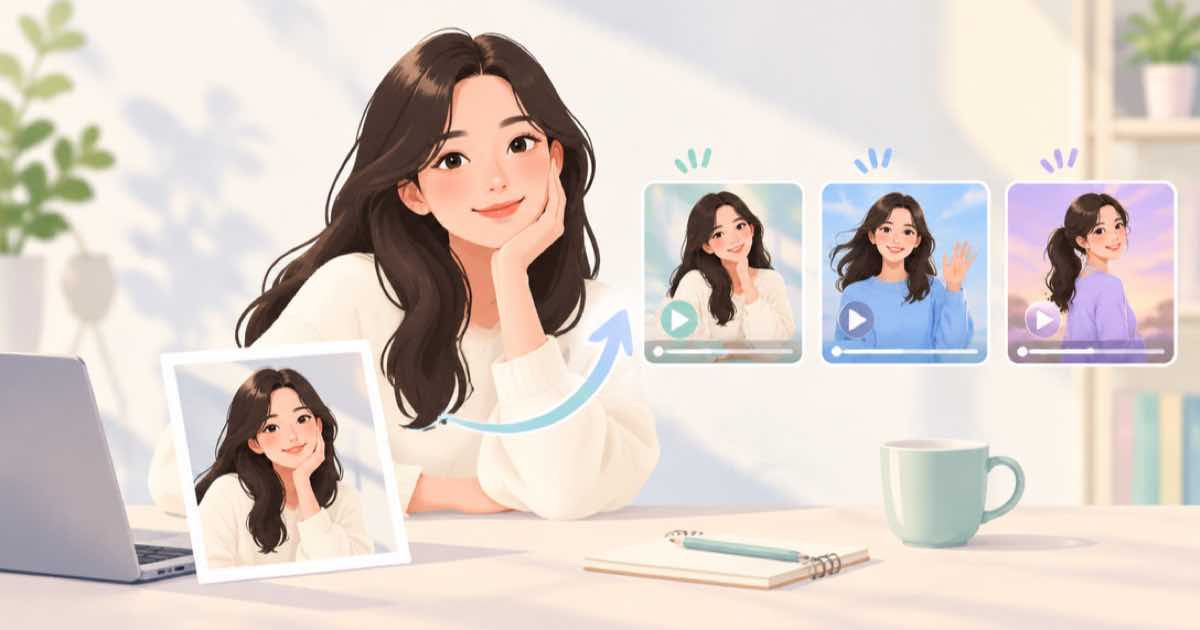
To lock the look, make one image you approve, and pass it as the first_frame in frame_images to each video model you want to try. All three clips start on the same picture, so the character, the clothes and the set match, and only the motion differs. On Sume that is wan-3.0, kling-3 and minimax-h3-max through the same POST /v1/videos body with a different model value.
The same trick works in the other direction. Once you have chosen a model, keep the image and make several clips from it with different prompts, and the whole set matches. That is how a short series with a recurring character is built from one approved picture instead of from luck.
This turns model choice into a fair test. If each model started from its own text prompt, you would be comparing both the model and its interpretation of the words.
Step one: the still
Make the image with the image API at POST /v1/images, with a public model id such as google/nano-banana-2.1, or use a photo you own. Check it at full size for faces, hands and any text, because every frame of every clip inherits what is wrong in it. Pick a framing with headroom, since the models will move the camera or the subject and a tight crop leaves nothing to move into.
Match the image to the aspect ratio you will request. Gemini Omni Flash 1.1 takes only 16:9 and 9:16, and other models list their own ratios in supported_aspect_ratios, so choose a ratio that all your candidate models accept.
Step two: one body, three model ids
Run the loop below with an Idempotency-Key per model, so that you can retry one model without creating a duplicate of another. Each call returns an id; poll each one, or add a callback_url to the body, and download the three files when they finish. Keep the file names tied to the model id so the comparison stays honest when you review them a day later.
Use the same prompt, the same duration and the same first frame. Change only model and, if needed, the resolution. The duration must be inside every model's window, which for these three means 5 to 15 seconds.
for m in wan-3.0 kling-3 minimax-h3-max; do
  curl -s -X POST "https://api.sume.com/v1/videos" \
    -H "Authorization: Bearer $SUME_API_KEY" \
    -H "Idempotency-Key: look-lock-$m-v1" \
    -H "Content-Type: application/json" \
    -d '{
      "model": "'"$m"'",
      "prompt": "Slow push-in, she turns toward the window",
      "duration": 6,
      "resolution": "720p",
      "frame_images": [{
        "type": "image_url", "frame_type": "first_frame",
        "image_url": {"url": "https://example.com/approved.png"}
      }]
    }'
done
What differs between the three
The catalog rows give the facts that matter for the comparison. Note that H3 Max resolution is 768p and not 720p, so request the nearest tier it lists.
| Model id | Window | Resolutions | Notes |
|---|---|---|---|
| wan-3.0 | 2 to 30 s | 480p, 720p, 1080p | Audio listed; list rates $0.05, $0.10, $0.20 per s |
| kling-3 | 4 to 15 s | 720p, 1080p | No reference inputs |
| minimax-h3-max | 5 to 15 s | 480p, 768p, 1080p | Native stereo audio, no toggle; 768p is native |
Reading the three results
Resist the urge to change the prompt between runs. If the prompt differs, the comparison is no longer about the model. Change one variable at a time: first the model, then, for the one you keep, the prompt, then the length. A table of your own notes with one row per run is enough, and it makes the choice easy to explain to a client or a teammate who was not there.
Compare the clips on what the image fixed and what it did not. Check whether the face holds for the whole clip, whether the clothing and the set stay the same, and whether the motion matches the prompt. Then compare what the models added: sound, camera movement and speed. Pick the one whose motion you want and re-run that model for the final length. If the clips drift from the image, shorten the clip or simplify the prompt, since long clips give a model more time to move away from its first frame.
For the full list of input limits per model, see the reference limits table.
Sources
Related posts
More in Use cases
- Lofi rain-on-window loop with sound: Gemini Omni 10 seconds
Make a 10-second lofi rainy window clip with Gemini Omni on Sume. Ambient audio wording, one image as first and last frame for a loop, and the cost to draft.
- Cut a long talk into short vertical clips with the Sume API
Turn one long recording into short clips on Sume: video-inspect for a sentence transcript, video-trim per range, video-captions to burn the words. Rates inside.
- Macro liquid pour video prompt for Gemini Omni and its price
A prompt recipe for a macro pour shot (oil, serum, honey) with Gemini Omni Flash on Sume: camera words, sound line, 5-second cost at 360p, 720p and 1080p.
- A 2.5% word error rate is 25 wrong words per 1,000: plan the proofread
If a 2.5% WER held on your audio, a 1,000-word transcript would still carry about 25 wrong words. How to proofread and burn captions on Sume with script_text.
Written by Sume